How to Build an LLM RAG Pipeline with Next.js and FastAPI
Step-by-step guide to building a production-ready Retrieval-Augmented Generation (RAG) system using Next.js on the frontend and FastAPI on the backend.

Retrieval-Augmented Generation (RAG) connects LLMs to custom datasets. In this comprehensive guide, you'll learn the architecture, code, and implementation steps required to build a secure, full-stack RAG application using a Next.js client and a FastAPI server.
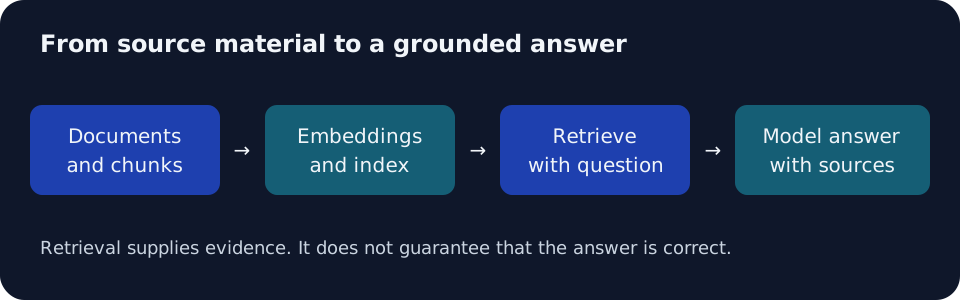
The retrieval stage supplies evidence to the model; source inspection and answer evaluation remain necessary.
Understanding RAG Architecture
A typical RAG pipeline is split into three main components: ingestion, retrieval, and generation. The ingestion step involves chunking documents, embedding them using a vectorizer, and storing them in a database. When a user asks a question, the retrieval system finds the most similar chunks, which are then passed alongside the query to the LLM to generate a grounded response.
Designing the Ingestion Pipeline
To parse documents effectively, we must select appropriate chunking strategies. Semantic chunking or recursive character splitting are the two most reliable approaches. A poor chunking strategy leads to lost context, while an overly large chunk size introduces noise. Standardizing the chunk size to 500 tokens with a 10% overlap is a solid starting point for most text corpora.
Setting Up the FastAPI Backend
FastAPI is the ideal backend framework for Python due to its high performance and automatic documentation generation. You'll write endpoints that accept query parameters, query a local vector store like ChromaDB, and stream the generated response from OpenAI or local Hugging Face models using Server-Sent Events (SSE).
Building the Next.js Chat Interface
The frontend must handle user inputs, display chat history, and stream responses in real-time. React Server Components and Hooks make it straightforward to build an interactive, responsive chat UI. Using Tailwind CSS ensures the interface remains polished and matches modern dark mode design patterns.
Securing and Optimizing the Pipeline
Deploying RAG to production requires caching strategies, prompt templates, and rate limiting. Implementing Redis caching for semantic queries can reduce API costs by up to 30%, while rate-limiting protects the backend from malicious traffic.
FastAPI RAG Chat Endpoint
from fastapi import FastAPI
from pydantic import BaseModel
from langchain_openai import OpenAIEmbeddings, ChatOpenAI
from langchain_community.vectorstores import Chroma

app = FastAPI()

class Query(BaseModel):
    text: str

@app.post("/api/query")
async def query_rag(query: Query):
    embeddings = OpenAIEmbeddings()
    db = Chroma(persist_directory="./chroma_db", embedding_function=embeddings)
    docs = db.similarity_search(query.text, k=3)
    context = "\n".join([doc.page_content for doc in docs])

    llm = ChatOpenAI(model="gpt-4-turbo")
    response = llm.predict(f"Context: {context}\nQuery: {query.text}")
    return {"answer": response}
Frequently Asked Questions
Which vector database is best for local development?
ChromaDB is the best choice for development because of its ease of installation and simplicity. For production workloads, Qdrant or Pinecone are better suited.
How do you prevent hallucination in RAG?
Strictly constrain the prompt template, instruct the model to only use the provided context, and return a default "I don't know" response if no relevant documents are found.